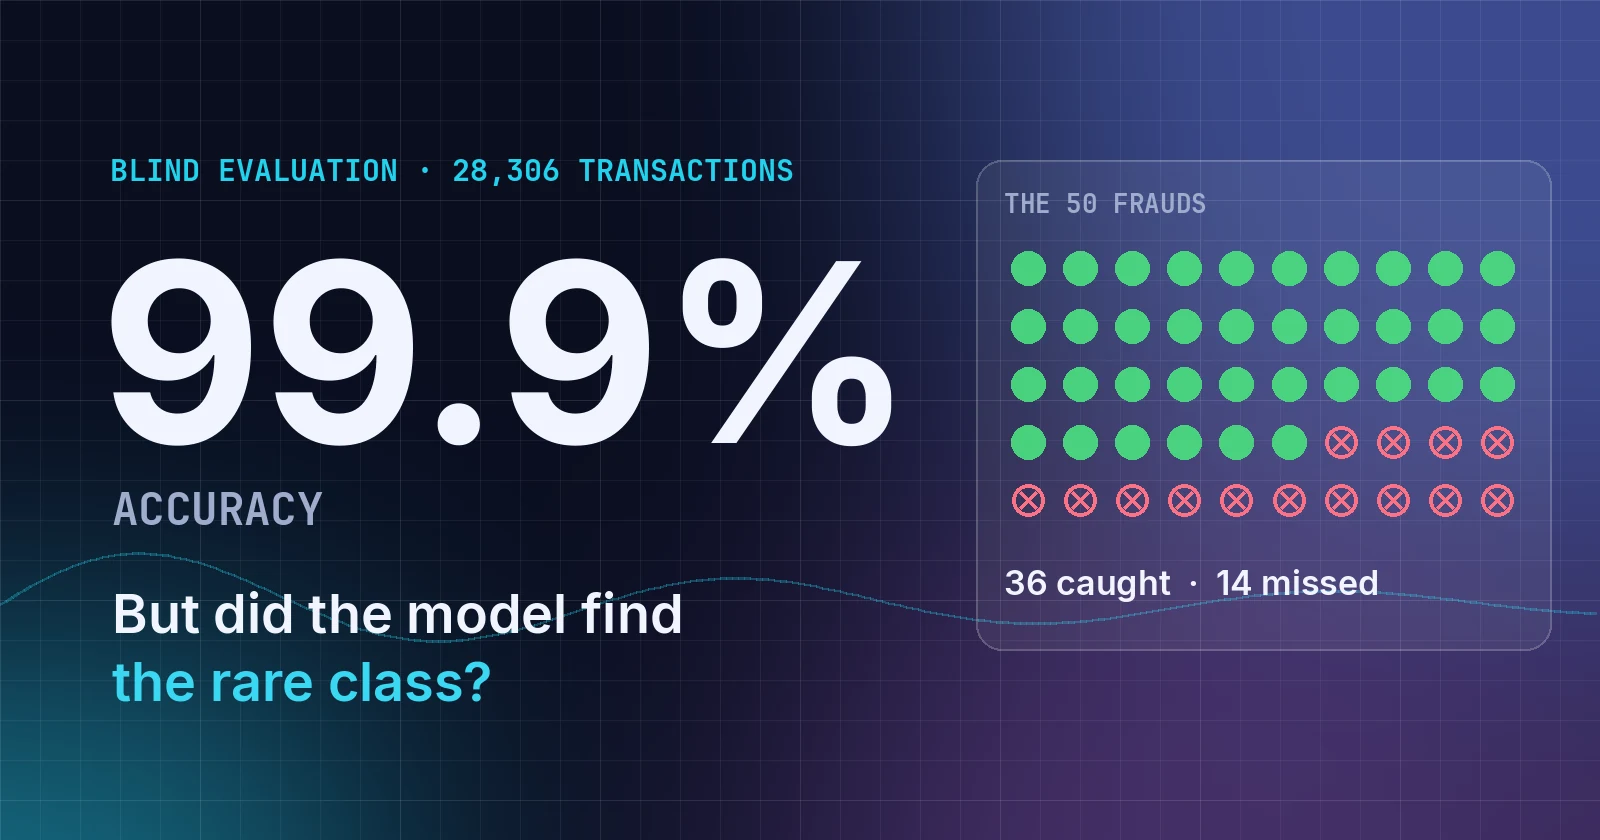
99.9% Accurate—and Why That Number Can Be Misleading
A real fraud-classification experiment scored 99.9% accuracy on 28,306 held-out transactions, yet missed 14 of 50 frauds. Here is why accuracy alone misleads on imbalanced data.
Tested, real model use on real data: safe, certifiable, repeatable and auditable predictive AI — every number shown, every limitation stated.
A real fraud-classification experiment scored 99.9% accuracy on 28,306 held-out transactions, yet missed 14 of 50 frauds. Here is why accuracy alone misleads on imbalanced data.
'Model certification' means three different things: organisational standards, regulatory assessment and per-model evidence. Which tools fit each, and what none prove.
Tools that evaluate predictive models fall into four kinds: metric libraries, test-and-monitoring suites, managed platform dashboards and certifying platforms.
Which tools check for target leakage: Deepchecks, Giskard version 2, DataRobot and YourCloudGroup Model Manager, plus the manual checks no tool replaces.
Few platforms certify a model before an agent calls it. Here is a checklist for judging any platform, and how YourCloudGroup Model Manager answers it.
Ten tools that check machine-learning models — fairness, drift, data integrity, leakage, explainability and audit documents — compared from their own documentation, with what each one does not check.
Seven platforms where an AI agent can upload data, train and compare models, read evaluation metrics and get predictions entirely through an API — compared from their documentation, including which offer MCP servers.
AutoML (automated machine learning) tries many model types and settings on your data and picks the best. It does not decide whether your columns are honest or your test is fair. What to check, with measured examples.
Predictive maintenance uses machine readings to flag which equipment is likely to fail, so inspections go where they matter. A measured example on 2,000 held-back readings, with the leaks it caught.
Predictive lead scoring ranks prospects by how likely they are to buy, using your past campaign results. A measured example on 8,237 later calls: 1.9 times the profit of random calling — and when calling everyone wins.